This post explores writing formally verified ML code in Lean.
Since the cost of proofs is declining rapidly and the amount of code generated
is skyrocketing, the value of verified code seems likely to climb.
While understanding proofs remains challenging, collaborating with AI to get
proofs of easy-to-understand properties seems like a natural middle ground.
The goal of this post is to verify foundational properties of Transformers.
These are critical properties that are used for
parallelization and optimization, including tensor parallelism, data parallelism,
batch invariance, permutation invariance, correctness of tiling, and locality
of sparse attention models. Code is available at srush/lean-transformer .
The text, comments, and structure of the blog are all human-written;
the proofs are all written by AI. Hopefully it can also serve as an advanced
intro to Lean.
This project is inspired by TorchLean ,
Verified Deep Learning with Lean 4 ,
and the Dex Programming Language .
Invariance and Equivariance
Different neural network architectures retain different properties of their input.
We generally classify these properties in terms of equivariance and invariance.
These allow researchers to reason about what they can learn, and
implementers to optimize computation while maintaining equivalence.
Our goal will be to prove equivariances and invariances for specific architectures.
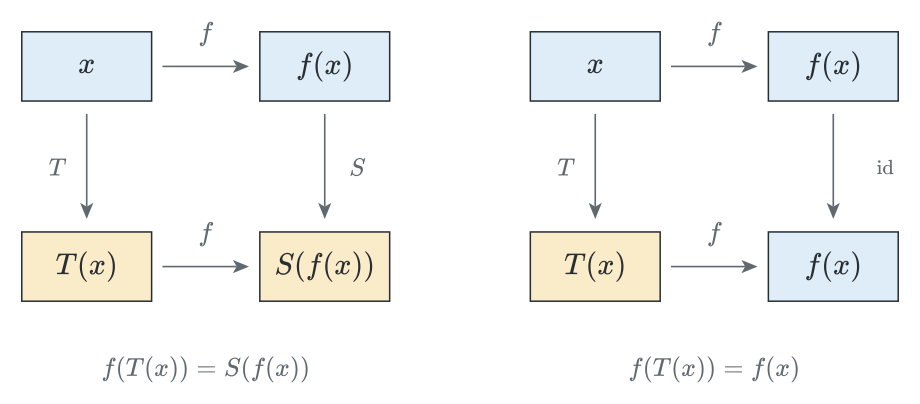
Notationally, ML definitions often assume the same functions can work on
different input shapes, e.g. batch sizes. For this reason, our Lean definition
will be a bit complex to allow for functions that are polymorphic over the shape.
def Equivariant
{ Shape : Type u }
{ Input : Shape → Type v } { Output : Shape → Type w }
( f : { shape : Shape } → Input shape → Output shape )
{ source target : Shape }
( T : Input source → Input target )
( S : Output source → Output target )
: Prop :=
∀ x , f ( T x ) = S ( f x ) def Invariant
{ Shape : Type u }
{ Input : Shape → Type v } { Output : Type w }
( f : { shape : Shape } → Input shape → Output )
{ source target : Shape }
( T : Input source → Input target ) : Prop :=
∀ x , f ( T x ) = f x
Vectors, Matrices, and Neural Networks
We begin by building a simple neural network library in Lean.
The relu function takes in a number and returns its non-negative part.
Along with the definition, we prove it does what we claim.
Following the style of
JAX ,
we lift scalar functions to operate on vectors.
Vectors (and tensors) are represented as higher-order functions mapping
indices to rational numbers. This makes our proofs easier since we do not
have to care about storage or efficiency.
abbrev Vector ( n : Nat ) := Fin n → Rat
def vector_of_tens_example : Vector 5 := fun _ => 10
def arange ( n : Nat ) : Vector n := fun i => i
variable { α : Type u } { β : Type v } { δ : Type w }
def vmap ( fn : α -> β ) { n : Nat } :
( ( Fin n -> α ) -> ( Fin n -> β ) ) :=
fun a => fun i => fn ( a i )
def vector_relu ( z : Vector n ) : Vector n :=
( vmap relu ) z
def vmap2 ( fn : α -> β -> δ ) : ( ( Fin n -> α ) -> ( Fin n -> β ) -> ( Fin n -> δ ) ) :=
fun a b => vmap ( fun i => fn ( a i ) ( b i ) ) id
instance : Add ( Vector n ) where
add := vmap2 ( fun a b => a + b )
instance : Mul ( Vector n ) where
mul := vmap2 ( fun a b => a * b )
For aggregations, we define a vector scan. Since we are using rationals for
simplicity, we do not have an exponential, so we define a "softmax-like"
nonlinear normalization instead.
abbrev fori { α : Type u } { n : Nat } ( f : Fin n → α ) : List α := List.ofFn f def scan ( step : σ → α → σ ) ( xs : Fin n → α ) ( initial : σ ) : σ :=
Fin.foldl n ( fun state i => step state ( xs i ) ) initial
def Vector.sum ( a : Vector n ) : Rat :=
( fori ( fun i => a i ) ) . sum def softmax_like ( z : Vector n ) : Vector n :=
let weights : Vector n := vmap ( fun x => 1 + relu x ) z
let total := weights . sum
vmap ( fun w => w / total ) weights def Vector.dot_product ( a b : Vector n ) : Rat :=
( a * b ) . sum
As an exercise, let's look at a simple vector theorem. Click the square □
next to each line of the proof and it will show you the current proof state.
The proof state divides the context from the goal ⊢. Each step will transform
these terms until we can construct the goal.
Matrices are defined similarly. We are basically just stacking
vmap calls to get our core operations. Note the implementation of matmul
in particular, which will be the target of future proofs.
We now have the full machinery of deep learning.
A neural network is just stacking layers and applying a simple loss function.
def forward ( layer : Matrix hidden hidden ) { batch : Nat }
( input : Matrix batch hidden ) :
Matrix batch hidden :=
( vmap ( vmap relu ) ) ( input . matmul layer ) abbrev Layer { Shape : Type v } ( State : Shape → Type u ) :=
{ shape : Shape } → State shape → State shape def neural_network { Shape : Type v } { State : Shape → Type u }
( layers : List ( Layer State ) ) : Layer State :=
fun input => layers . foldl ( fun state layer => layer state ) input def loss ( point_loss : Fin batch → Vector hidden → Rat )
( matrix : Matrix batch hidden ) : Rat :=
Vector.sum ( vmap2 point_loss id matrix )
Properties of Neural Networks
Now let us return to our goal of proving network equivariances.
Our strategy will be to first show that in general equivariances compose,
and then show that they propagate through a neural network.
theorem Equivariant.comp
{ Shape : Type u }
{ A : Shape → Type v } { B : Shape → Type w } { C : Shape → Type z }
{ first : { shape : Shape } → A shape → B shape }
{ next : { shape : Shape } → B shape → C shape }
{ source target : Shape }
{ T : A source → A target } { S : B source → B target }
{ U : C source → C target }
( hfirst : Equivariant ( Input := A ) ( Output := B ) first T S )
( hnext : Equivariant ( Input := B ) ( Output := C ) next S U ) :
Equivariant ( Input := A ) ( Output := C )
( fun input => next ( first input ) ) T U := by Shape : Type u A : Shape → Type v B : Shape → Type w C : Shape → Type z first : { shape : Shape } → A shape → B shape next : { shape : Shape } → B shape → C shape source : Shape target : Shape T : A source → A target S : B source → B target U : C source → C target hfirst : Equivariant (fun { shape } => first ) T S hnext : Equivariant (fun { shape } => next ) S U ⊢ Equivariant (fun { shape } input => next ( first input ) ) T U
intro input Shape : Type u A : Shape → Type v B : Shape → Type w C : Shape → Type z first : { shape : Shape } → A shape → B shape next : { shape : Shape } → B shape → C shape source : Shape target : Shape T : A source → A target S : B source → B target U : C source → C target hfirst : Equivariant (fun { shape } => first ) T S hnext : Equivariant (fun { shape } => next ) S U input : A source ⊢ (fun { shape } input => next ( first input ) ) ( T input ) = U ( (fun { shape } input => next ( first input ) ) input )
exact ( congrArg next ( hfirst input ) ) . trans ( hnext ( first input ) ) All goals completed! 🐙
theorem Equivariant.prod
{ Shape : Type u }
{ Input₁ : Shape → Type u₁ } { Input₂ : Shape → Type u₂ }
{ Output₁ : Shape → Type v₁ } { Output₂ : Shape → Type v₂ }
{ f : { shape : Shape } → Input₁ shape → Output₁ shape }
{ g : { shape : Shape } → Input₂ shape → Output₂ shape }
{ source target : Shape }
{ T₁ : Input₁ source → Input₁ target } { S₁ : Output₁ source → Output₁ target }
{ T₂ : Input₂ source → Input₂ target } { S₂ : Output₂ source → Output₂ target }
( hf : Equivariant ( Input := Input₁ ) ( Output := Output₁ ) f T₁ S₁ )
( hg : Equivariant ( Input := Input₂ ) ( Output := Output₂ ) g T₂ S₂ ) :
Equivariant ( Input := fun shape => Input₁ shape × Input₂ shape )
( Output := fun shape => Output₁ shape × Output₂ shape )
( fun input => Prod.map f g input ) ( Prod.map T₁ T₂ ) ( Prod.map S₁ S₂ ) := by Shape : Type u Input₁ : Shape → Type u₁ Input₂ : Shape → Type u₂ Output₁ : Shape → Type v₁ Output₂ : Shape → Type v₂ f : { shape : Shape } → Input₁ shape → Output₁ shape g : { shape : Shape } → Input₂ shape → Output₂ shape source : Shape target : Shape T₁ : Input₁ source → Input₁ target S₁ : Output₁ source → Output₁ target T₂ : Input₂ source → Input₂ target S₂ : Output₂ source → Output₂ target hf : Equivariant (fun { shape } => f ) T₁ S₁ hg : Equivariant (fun { shape } => g ) T₂ S₂ ⊢ Equivariant (fun { shape } input => Prod.map f g input ) ( Prod.map T₁ T₂ ) ( Prod.map S₁ S₂ )
intro x Shape : Type u Input₁ : Shape → Type u₁ Input₂ : Shape → Type u₂ Output₁ : Shape → Type v₁ Output₂ : Shape → Type v₂ f : { shape : Shape } → Input₁ shape → Output₁ shape g : { shape : Shape } → Input₂ shape → Output₂ shape source : Shape target : Shape T₁ : Input₁ source → Input₁ target S₁ : Output₁ source → Output₁ target T₂ : Input₂ source → Input₂ target S₂ : Output₂ source → Output₂ target hf : Equivariant (fun { shape } => f ) T₁ S₁ hg : Equivariant (fun { shape } => g ) T₂ S₂ x : Input₁ source × Input₂ source ⊢ (fun { shape } input => Prod.map f g input ) ( Prod.map T₁ T₂ x ) =
Prod.map S₁ S₂ ( (fun { shape } input => Prod.map f g input ) x )
exact Prod.ext ( hf x . 1 ) ( hg x . 2 ) All goals completed! 🐙
theorem neural_network_equivariant
{ Shape : Type v } { State : Shape → Type u } { source target : Shape }
( layers : List ( Layer State ) )
( transform : State source → State target )
( equivariant : ∀ layer ∈ layers ,
Equivariant ( Input := State ) ( Output := State )
layer transform transform ) :
Equivariant ( Input := State ) ( Output := State )
( neural_network layers ) transform transform := by Shape : Type v State : Shape → Type u source : Shape target : Shape layers : List ( Layer State ) transform : State source → State target equivariant : ∀ ( layer : Layer State ), layer ∈ layers → Equivariant (fun { shape } => layer ) transform transform ⊢ Equivariant (fun { shape } => neural_network layers ) transform transform
induction layers with
| nil => nil Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target equivariant : ∀ ( layer : Layer State ), layer ∈ [ ] → Equivariant (fun { shape } => layer ) transform transform ⊢ Equivariant (fun { shape } => neural_network [ ] ) transform transform intro input nil Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target equivariant : ∀ ( layer : Layer State ), layer ∈ [ ] → Equivariant (fun { shape } => layer ) transform transform input : State source ⊢ (fun { shape } => neural_network [ ] ) ( transform input ) = transform ( (fun { shape } => neural_network [ ] ) input ) ; rfl All goals completed! 🐙
| cons layer rest ih => cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform
have composed := Equivariant.comp ( equivariant layer ( by Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform ⊢ (fun { shape } => layer ) ∈ layer :: rest cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform composed : Equivariant (fun { shape } input => neural_network rest ( layer input ) ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform simp All goals completed! 🐙 cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform composed : Equivariant (fun { shape } input => neural_network rest ( layer input ) ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform ) )
( ih ( fun layer member => equivariant layer ( by Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer✝ : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform layer : Layer State member : layer ∈ rest ⊢ (fun { shape } => layer ) ∈ layer✝ :: rest cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform composed : Equivariant (fun { shape } input => neural_network rest ( layer input ) ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform simp [ member ] All goals completed! 🐙 cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform composed : Equivariant (fun { shape } input => neural_network rest ( layer input ) ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform ) ) ) cons Shape : Type v State : Shape → Type u source : Shape target : Shape transform : State source → State target layer : Layer State rest : List ( Layer State ) ih : (∀ ( layer : Layer State ), layer ∈ rest → Equivariant (fun { shape } => layer ) transform transform ) →
Equivariant (fun { shape } => neural_network rest ) transform transform equivariant : ∀ ( layer_1 : Layer State ), layer_1 ∈ layer :: rest → Equivariant (fun { shape } => layer_1 ) transform transform composed : Equivariant (fun { shape } input => neural_network rest ( layer input ) ) transform transform ⊢ Equivariant (fun { shape } => neural_network ( layer :: rest ) ) transform transform
exact composed All goals completed! 🐙
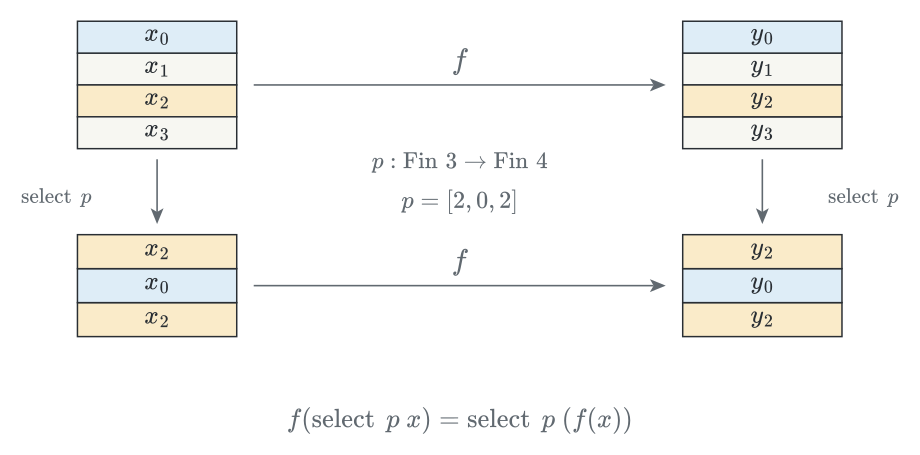
We can use these properties to show that our neural network
is selection equivariant, roughly that each individual result should be the
same no matter how batches are built or ordered.
From these individual results, we directly build up to our first main result.
A simple neural network does not depend on the order or content of its batch.
System Optimization
While these properties so far seem basic, they are essential for
designing large-scale LLMs. These properties provide the means for parallelizing
and optimizing these systems. They also are properties that are commonly broken when
new low-level optimizations are introduced. Let's look at a couple of these
in more detail.
Batch Invariance
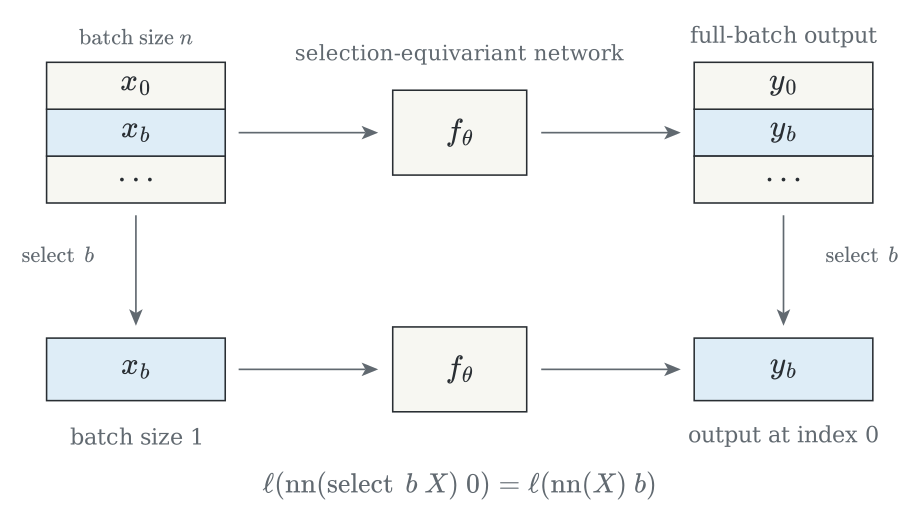
Batch invariance ensures that the final loss of the system is independent
of the size of the batch used. This property can ensure replicability across
systems. See
Horace He's
beautifully described blog about why batch invariance is useful and how it
is often sacrificed under different optimizations.
Here we prove that selection equivariance implies a simple form of batch
invariance. Basically, you get the same loss independent of the batch.
Tensor Parallel
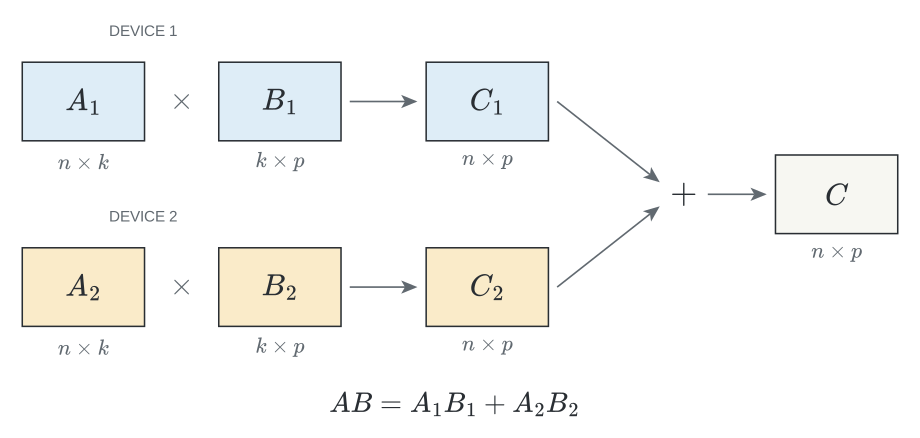
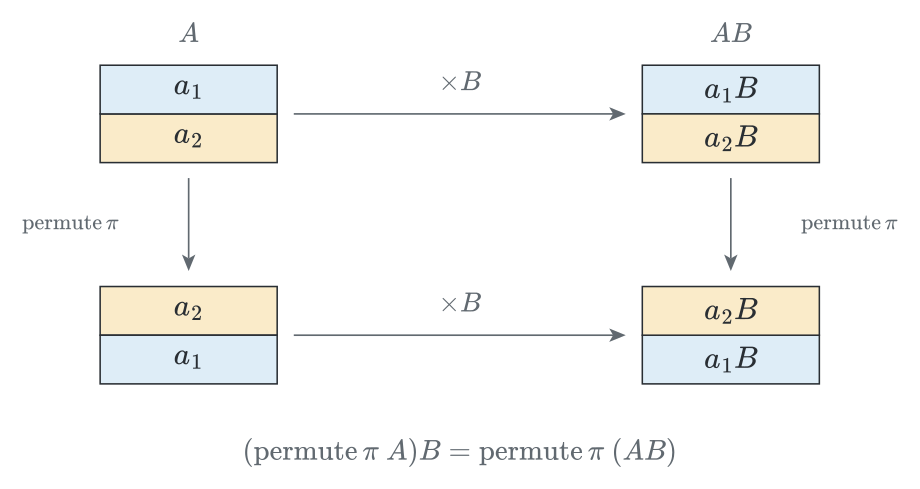
Tensor parallelism is a common optimization for distributed neural networks.
It's a fancy way of saying that instead of doing a matrix multiplication on one
host, you can instead split it into two or more parts, do those multiplications
separately, and then merge them.
Data Parallel
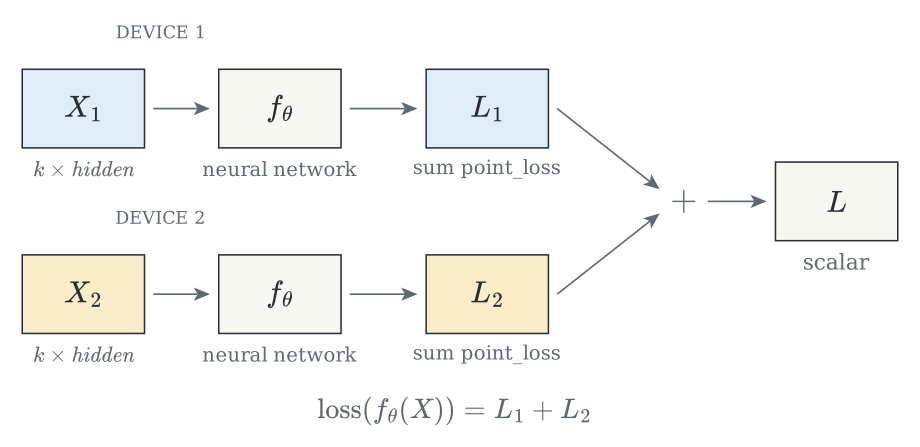
Data parallelism says that, in training, we can split the data into
different groups, run the full neural network and loss on different machines,
and then combine. We need to ensure that we get the same result
by running things separately as together.
theorem loss_row_split ( point_loss : Fin ( k + k ) → Vector hidden → Rat )
( output : Matrix ( k + k ) hidden ) :
loss ( fun b row => point_loss ( b . castAdd k ) row ) output . row_split . 1 +
loss ( fun b row => point_loss ( b . natAdd k ) row ) output . row_split . 2 =
loss point_loss output :=
Vector.sum_split ( fun b => point_loss b ( output b ) )
def data_parallel_loss
( layers : List ( Layer ( fun batch => Fin batch → Vector hidden ) ) )
( point_loss : Fin ( k + k ) → Vector hidden → Rat )
( input : Matrix ( k + k ) hidden ) : Rat :=
let ( first , second ) := input . row_split
loss ( fun b row => point_loss ( b . castAdd k ) row )
( neural_network layers first ) +
loss ( fun b row => point_loss ( b . natAdd k ) row )
( neural_network layers second ) theorem data_parallel_loss_correct
( layers : List ( Layer ( fun batch => Fin batch → Vector hidden ) ) )
( equivariant : ∀ layer ∈ layers , SelectionEquivariant layer )
( point_loss : Fin ( k + k ) → Vector hidden → Rat )
( input : Matrix ( k + k ) hidden ) :
data_parallel_loss layers point_loss input =
loss point_loss ( neural_network layers input ) := by hidden : Nat k : Nat layers : List ( Layer fun batch => Fin batch → Vector hidden ) equivariant : ∀ ( layer : Layer fun batch => Fin batch → Vector hidden ), layer ∈ layers → SelectionEquivariant fun { n } => layer point_loss : Fin ( k + k ) → Vector hidden → Rat input : Matrix ( k + k ) hidden ⊢ data_parallel_loss layers point_loss input = loss point_loss ( neural_network layers input )
dsimp only [ Matrix ] at input hidden : Nat k : Nat layers : List ( Layer fun batch => Fin batch → Vector hidden ) equivariant : ∀ ( layer : Layer fun batch => Fin batch → Vector hidden ), layer ∈ layers → SelectionEquivariant fun { n } => layer point_loss : Fin ( k + k ) → Vector hidden → Rat input : Fin ( k + k ) → Vector hidden ⊢ data_parallel_loss layers point_loss input = loss point_loss ( neural_network layers input )
have equiv := neural_network_selection_equivariant layers equivariant
( n := k + k ) ( m := k ) hidden : Nat k : Nat layers : List ( Layer fun batch => Fin batch → Vector hidden ) equivariant : ∀ ( layer : Layer fun batch => Fin batch → Vector hidden ), layer ∈ layers → SelectionEquivariant fun { n } => layer point_loss : Fin ( k + k ) → Vector hidden → Rat input : Fin ( k + k ) → Vector hidden equiv : ∀ ( selection : Fin k → Fin ( k + k ) ),
Equivariant (fun { shape } { n } => neural_network layers ) ( select selection ) ( select selection ) ⊢ data_parallel_loss layers point_loss input = loss point_loss ( neural_network layers input )
unfold Equivariant at equiv hidden : Nat k : Nat layers : List ( Layer fun batch => Fin batch → Vector hidden ) equivariant : ∀ ( layer : Layer fun batch => Fin batch → Vector hidden ), layer ∈ layers → SelectionEquivariant fun { n } => layer point_loss : Fin ( k + k ) → Vector hidden → Rat input : Fin ( k + k ) → Vector hidden equiv : ∀ ( selection : Fin k → Fin ( k + k ) ) ( x : (fun n => Fin n → Vector hidden ) ( k + k ) ),
(fun { shape } { n } => neural_network layers ) ( select selection x ) =
select selection ( (fun { shape } { n } => neural_network layers ) x ) ⊢ data_parallel_loss layers point_loss input = loss point_loss ( neural_network layers input )
simpa only [ data_parallel_loss , Matrix.row_split , equiv ] using
loss_row_split point_loss ( neural_network layers input ) All goals completed! 🐙
We next study a simple bidirectional Transformer with attention.
The sequence becomes an additional dimension of our tensor.
We first define attention.
Attention is included in the main network through a parameterized Transformer block.
One of the more surprising properties of the vanilla (bidirectional) Transformer
is that it is a set-to-set model, i.e. it is permutation equivariant in
sequence length. Let's define first what that means formally.
Most of the core operations we have defined have the necessary equivariance already.
The main additional property we need is for our softmax, which follows directly from
addition.
Now we can show that the vanilla Transformer is permutation equivariant.
Of course, in practice, we add additional information that breaks this property.
The simplest way is through the use of positional features. We can show that even
simple positional features break equivariance with a direct counterexample.
def position_features ( i : Rat ) : Vector 3 :=
fun d => if d . val = 0 then i else if d . val = 1 then i * i else 1 def Matrix.add_positions ( input : Matrix seq 3 ) : Matrix seq 3 :=
fun s => input s + position_features ( s . val : Rat )
theorem positional_transformer_breaks_permutation_equivariance :
let identity : Matrix 3 3 := fun i j => if i = j then 1 else 0
let block : TransformerBlock 3 := ⟨ identity , identity , identity , identity ⟩
let layers : List ( Layer ( fun seq => Matrix seq 3 ) ) :=
[ @ Matrix.add_positions ,
fun input => transformer_block attention_layer block input ]
¬ PermuteEquivariant ( n := 2 ) ( neural_network ( shape := 2 ) layers ) := by ⊢ let identity := fun i j => if i = j then 1 else 0 ;
let block := { weight := identity , wq := identity , wk := identity , wv := identity } ;
let layers := [ @ Matrix.add_positions , fun { shape } input => transformer_block attention_layer block input ] ;
¬ PermuteEquivariant ( neural_network layers ) permute permute
dsimp only ⊢ ¬ PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute
intro equivariant equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute ⊢ False
let input : Matrix 2 3 := fun s d => if d . val = 0 then ( s . val : Rat ) else 0 equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 ⊢ False
let swap : PositionPermutation 2 :=
⟨ fun s => ⟨ 1 - s . val , by equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 s : Fin 2 ⊢ 1 - ↑ s < 2 equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ False omega All goals completed! 🐙 equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ False ⟩ , by equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 ⊢ ( fori fun s => ⟨ 1 - ↑ s , ⋯ ⟩ ) . Perm ( fori fun i => i ) equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ False decide All goals completed! 🐙 equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ False ⟩ equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ False
have same := congrArg ( fun output => output 0 0 ) ( equivariant swap input ) equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } same : (fun { shape } =>
neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
( permute swap input ) 0 0 =
permute swap
( (fun { shape } =>
neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
input )
0 0 ⊢ False
revert same equivariant : PermuteEquivariant
( neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
permute permute input : Matrix 2 3 := fun s d => if ↑ d = 0 then ↑ ↑ s else 0 swap : PositionPermutation 2 := { index := fun s => ⟨ 1 - ↑ s , ⋯ ⟩ , valid := ⋯ } ⊢ (fun { shape } =>
neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
( permute swap input ) 0 0 =
permute swap
( (fun { shape } =>
neural_network
[ @ Matrix.add_positions , fun { shape } input =>
transformer_block attention_layer
{ weight := fun i j => if i = j then 1 else 0 , wq := fun i j => if i = j then 1 else 0 ,
wk := fun i j => if i = j then 1 else 0 , wv := fun i j => if i = j then 1 else 0 }
input ] )
input )
0 0 →
False
decide + kernel All goals completed! 🐙
Sparse Attention
An alternative to full attention over the sequence is a sparse
attention over a local region. Sliding window attention
only looks at the surrounding window. We implement this with a
windowed mask.
abbrev InWindow ( radius : Nat ) ( s t : Fin seq ) : Prop :=
s . val ≤ t . val + radius ∧ t . val ≤ s . val + radius def window_mask ( radius : Nat ) : Matrix seq seq :=
fun s t => if InWindow radius s t then 1 else 0 def matrix_mask ( radius : Nat ) ( a : Matrix m m ) : Matrix m m :=
let mask : Matrix m m := window_mask radius
a * mask def swa ( radius : Nat ) : Mixer seq hidden :=
base_attention ( matrix_mask radius )
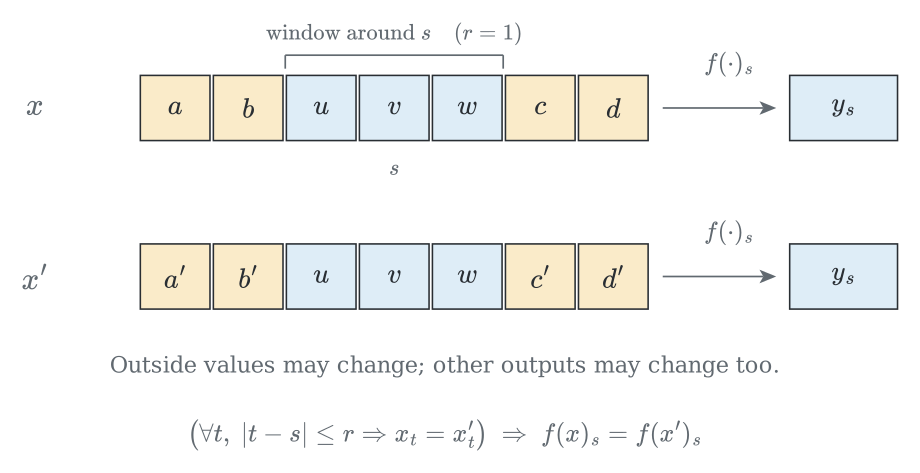
The sliding window has the property that each position is only impacted by
the region around it. We formalize this idea below.
def RegionInvariant ( radius : Nat )
( op : ( Fin seq → α ) → Fin seq → β ) : Prop :=
∀ ( input other : Fin seq → α ) ( s : Fin seq ) ,
( ∀ t , InWindow radius s t → input t = other t ) →
op input s = op other s
theorem SelectionEquivariant.region_invariant
{ op : { n : Nat } → ( Fin n → α ) → ( Fin n → β ) }
( equivariant : SelectionEquivariant op ) :
RegionInvariant ( seq := seq ) 0 op := by α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op ⊢ RegionInvariant 0 op
intro a other i agree α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ op a i = op other i
have same := agree i ( by α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ InWindow 0 i i α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op a i = op other i constructor left α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ ↑ i ≤ ↑ i + 0 right α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ ↑ i ≤ ↑ i + 0 α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op a i = op other i <;> left α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ ↑ i ≤ ↑ i + 0 right α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t ⊢ ↑ i ≤ ↑ i + 0 α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op a i = op other i omega All goals completed! 🐙 α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op a i = op other i ) α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op a i = op other i
calc
op a i = op ( fun _ : Fin 1 => a i ) 0 :=
( congrFun ( equivariant ( fun _ : Fin 1 => i ) a ) 0 ) . symm
_ = op ( fun _ : Fin 1 => other i ) 0 := by α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op (fun x => a i ) 0 = op (fun x => other i ) 0 rw [ same α : Type u β : Type v seq : Nat op : { n : Nat } → ( Fin n → α ) → Fin n → β equivariant : SelectionEquivariant fun { n } => op a : Fin seq → α other : Fin seq → α i : Fin seq agree : ∀ ( t : Fin seq ), InWindow 0 i t → a t = other t same : a i = other i ⊢ op (fun x => other i ) 0 = op (fun x => other i ) 0 All goals completed! 🐙 ] All goals completed! 🐙
_ = op other i := congrFun ( equivariant ( fun _ : Fin 1 => i ) other ) 0
theorem vmap_region_invariant ( fn : α → β ) :
RegionInvariant ( seq := seq ) 0 ( vmap fn ) :=
SelectionEquivariant.region_invariant ( vmap_selection_equivariant fn )
The interesting new aspect of region invariance will be how it composes.
Region invariance is additive under composition.
theorem RegionInvariant.comp
{ first : ( Fin seq → α ) → Fin seq → β }
{ second : ( Fin seq → β ) → Fin seq → δ }
( hfirst : RegionInvariant r first ) ( hsecond : RegionInvariant t second ) :
RegionInvariant ( r + t ) ( fun input => second ( first input ) ) := by α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second ⊢ RegionInvariant ( r + t ) fun input => second ( first input )
intro input other s agree α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 ⊢ (fun input => second ( first input ) ) input s = (fun input => second ( first input ) ) other s
apply hsecond α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 ⊢ ∀ ( t_1 : Fin seq ), InWindow t s t_1 → first input t_1 = first other t_1
intro u hu α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : InWindow t s u ⊢ first input u = first other u
apply hfirst α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : InWindow t s u ⊢ ∀ ( t : Fin seq ), InWindow r u t → input t = other t
intro v hv α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : InWindow t s u v : Fin seq hv : InWindow r u v ⊢ input v = other v
apply agree α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : InWindow t s u v : Fin seq hv : InWindow r u v ⊢ InWindow ( r + t ) s v
dsimp [ InWindow ] at hu hv ⊢ α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : ↑ s ≤ ↑ u + t ∧ ↑ u ≤ ↑ s + t v : Fin seq hv : ↑ u ≤ ↑ v + r ∧ ↑ v ≤ ↑ u + r ⊢ ↑ s ≤ ↑ v + ( r + t ) ∧ ↑ v ≤ ↑ s + ( r + t )
constructor left α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : ↑ s ≤ ↑ u + t ∧ ↑ u ≤ ↑ s + t v : Fin seq hv : ↑ u ≤ ↑ v + r ∧ ↑ v ≤ ↑ u + r ⊢ ↑ s ≤ ↑ v + ( r + t ) right α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : ↑ s ≤ ↑ u + t ∧ ↑ u ≤ ↑ s + t v : Fin seq hv : ↑ u ≤ ↑ v + r ∧ ↑ v ≤ ↑ u + r ⊢ ↑ v ≤ ↑ s + ( r + t ) <;> left α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : ↑ s ≤ ↑ u + t ∧ ↑ u ≤ ↑ s + t v : Fin seq hv : ↑ u ≤ ↑ v + r ∧ ↑ v ≤ ↑ u + r ⊢ ↑ s ≤ ↑ v + ( r + t ) right α : Type u β : Type v δ : Type w seq : Nat r : Nat t : Nat first : ( Fin seq → α ) → Fin seq → β second : ( Fin seq → β ) → Fin seq → δ hfirst : RegionInvariant r first hsecond : RegionInvariant t second input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t_1 : Fin seq ), InWindow ( r + t ) s t_1 → input t_1 = other t_1 u : Fin seq hu : ↑ s ≤ ↑ u + t ∧ ↑ u ≤ ↑ s + t v : Fin seq hv : ↑ u ≤ ↑ v + r ∧ ↑ v ≤ ↑ u + r ⊢ ↑ v ≤ ↑ s + ( r + t ) omega All goals completed! 🐙
theorem neural_network_region_invariant ( radius : Nat )
( layers : List ( Layer ( fun seq => Fin seq → α ) ) )
( invariant : ∀ layer ∈ layers , RegionInvariant radius ( @ layer seq ) ) :
RegionInvariant ( seq := seq ) ( layers . length * radius )
( neural_network layers ) := by α : Type u seq : Nat radius : Nat layers : List ( Layer fun seq => Fin seq → α ) invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ layers → RegionInvariant radius layer ⊢ RegionInvariant ( layers . length * radius ) ( neural_network layers )
induction layers with
| nil => nil α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer ⊢ RegionInvariant ( [ ] . length * radius ) ( neural_network [ ] )
intro input other s agree nil α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ neural_network [ ] input s = neural_network [ ] other s
exact agree s ( by α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ InWindow ( [ ] . length * radius ) s s constructor left α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ ↑ s ≤ ↑ s + [ ] . length * radius right α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ ↑ s ≤ ↑ s + [ ] . length * radius <;> left α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ ↑ s ≤ ↑ s + [ ] . length * radius right α : Type u seq : Nat radius : Nat invariant : ∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ [ ] → RegionInvariant radius layer input : Fin seq → α other : Fin seq → α s : Fin seq agree : ∀ ( t : Fin seq ), InWindow ( [ ] . length * radius ) s t → input t = other t ⊢ ↑ s ≤ ↑ s + [ ] . length * radius omega All goals completed! 🐙 )
| cons layer rest ih => cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) )
have composed := RegionInvariant.comp ( invariant @ layer ( by α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 ⊢ layer ∈ layer :: rest cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 composed : RegionInvariant ( radius + rest . length * radius ) fun input => neural_network rest ( layer input ) ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) ) simp All goals completed! 🐙 cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 composed : RegionInvariant ( radius + rest . length * radius ) fun input => neural_network rest ( layer input ) ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) ) ) )
( ih ( fun layer member => invariant @ layer ( by α : Type u seq : Nat radius : Nat layer✝ : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 layer : Layer fun seq => Fin seq → α member : layer ∈ rest ⊢ layer ∈ layer✝ :: rest cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 composed : RegionInvariant ( radius + rest . length * radius ) fun input => neural_network rest ( layer input ) ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) ) simp [ member ] All goals completed! 🐙 cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 composed : RegionInvariant ( radius + rest . length * radius ) fun input => neural_network rest ( layer input ) ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) ) ) ) ) cons α : Type u seq : Nat radius : Nat layer : Layer fun seq => Fin seq → α rest : List ( Layer fun seq => Fin seq → α ) ih : (∀ ( layer : Layer fun seq => Fin seq → α ), layer ∈ rest → RegionInvariant radius layer ) →
RegionInvariant ( rest . length * radius ) ( neural_network rest ) invariant : ∀ ( layer_1 : Layer fun seq => Fin seq → α ), layer_1 ∈ layer :: rest → RegionInvariant radius layer_1 composed : RegionInvariant ( radius + rest . length * radius ) fun input => neural_network rest ( layer input ) ⊢ RegionInvariant ( ( layer :: rest ) . length * radius ) ( neural_network ( layer :: rest ) )
simpa only [ RegionInvariant , List.length_cons ,
Nat.add_mul , Nat.one_mul , Nat.add_comm ,
neural_network , List.foldl_cons ] using composed All goals completed! 🐙
Finally, we need to show the radius of SWA. We first show that our implementation
of masking leads to a given radius and then apply this to the sparse attention
implementation.
attribute [ local simp ] Rat.add_zero Rat.zero_add Rat.zero_mul Rat.mul_zero
theorem Matrix.masked_matmul_region_invariant ( radius : Nat )
( weights : Matrix seq seq ) :
RegionInvariant radius ( fun values : Matrix seq hidden =>
( matrix_mask radius weights ) . matmul values ) := by seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq ⊢ RegionInvariant radius fun values => ( matrix_mask radius weights ) . matmul values
intro input other s agree seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ (fun values => ( matrix_mask radius weights ) . matmul values ) input s =
(fun values => ( matrix_mask radius weights ) . matmul values ) other s
funext j seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden ⊢ (fun values => ( matrix_mask radius weights ) . matmul values ) input s j =
(fun values => ( matrix_mask radius weights ) . matmul values ) other s j
apply congrArg Vector.sum seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden ⊢ matrix_mask radius weights s * transpose input j = matrix_mask radius weights s * transpose other j
funext t seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ⊢ ( matrix_mask radius weights s * transpose input j ) t = ( matrix_mask radius weights s * transpose other j ) t
change weights s t * window_mask radius s t * input t j =
weights s t * window_mask radius s t * other t j seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ⊢ weights s t * window_mask radius s t * input t j = weights s t * window_mask radius s t * other t j
by_cases ht : InWindow radius s t pos seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ht : InWindow radius s t ⊢ weights s t * window_mask radius s t * input t j = weights s t * window_mask radius s t * other t j neg seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ht : ¬ InWindow radius s t ⊢ weights s t * window_mask radius s t * input t j = weights s t * window_mask radius s t * other t j
· pos seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ht : InWindow radius s t ⊢ weights s t * window_mask radius s t * input t j = weights s t * window_mask radius s t * other t j rw [ agree t ht pos seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ht : InWindow radius s t ⊢ weights s t * window_mask radius s t * other t j = weights s t * window_mask radius s t * other t j All goals completed! 🐙 ] All goals completed! 🐙
· neg seq : Nat hidden : Nat radius : Nat weights : Matrix seq seq input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t j : Fin hidden t : Fin seq ht : ¬ InWindow radius s t ⊢ weights s t * window_mask radius s t * input t j = weights s t * window_mask radius s t * other t j simp [ window_mask , ht ] All goals completed! 🐙
theorem swa_region_invariant ( radius : Nat ) ( wq wk wv : Matrix hidden hidden ) :
RegionInvariant ( seq := seq ) radius
( fun input => swa radius ( project_qkv input wq wk wv ) ) := by hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden ⊢ RegionInvariant radius fun input => swa radius ( project_qkv input wq wk wv )
intro input other s agree hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
have center := agree s ( by hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ InWindow radius s s hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s constructor left hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ ↑ s ≤ ↑ s + radius right hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ ↑ s ≤ ↑ s + radius hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s <;> left hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ ↑ s ≤ ↑ s + radius right hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t ⊢ ↑ s ≤ ↑ s + radius hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s omega All goals completed! 🐙 hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
let contribution ( query row : Vector hidden ) : Vector hidden := fun j =>
Vector.dot_product ( fun d => query . dot_product ( wq . transpose d ) )
( fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
have masked ( x : Matrix seq hidden ) :
swa radius ( project_qkv x wq wk wv ) s =
( matrix_mask radius ( fun _ _ => 1 ) ) . matmul
( vmap ( contribution ( x s ) ) x ) s := by hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden ⊢ RegionInvariant radius fun input => swa radius ( project_qkv input wq wk wv ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
funext j hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) x : Matrix seq hidden j : Fin hidden ⊢ swa radius ( project_qkv x wq wk wv ) s j = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s j hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
apply congrArg Vector.sum hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) x : Matrix seq hidden j : Fin hidden ⊢ matrix_mask radius ( ( x . matmul wq ) . matmul ( x . matmul wk ) . transpose ) s * ( x . matmul wv ) . transpose j =
matrix_mask radius (fun x x_1 => 1 ) s * Matrix.transpose ( vmap ( contribution ( x s ) ) x ) j hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
funext t hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) x : Matrix seq hidden j : Fin hidden t : Fin seq ⊢ ( matrix_mask radius ( ( x . matmul wq ) . matmul ( x . matmul wk ) . transpose ) s * ( x . matmul wv ) . transpose j ) t =
( matrix_mask radius (fun x x_1 => 1 ) s * Matrix.transpose ( vmap ( contribution ( x s ) ) x ) j ) t hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
exact ( show ∀ a b c : Rat , a * b * c = ( 1 * b ) * ( a * c ) by hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden ⊢ RegionInvariant radius fun input => swa radius ( project_qkv input wq wk wv ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
intros hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) x : Matrix seq hidden j : Fin hidden t : Fin seq a✝ : Rat b✝ : Rat c✝ : Rat ⊢ a✝ * b✝ * c✝ = 1 * b✝ * ( a✝ * c✝ ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s ; grind All goals completed! 🐙 hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s ) _ _ _ hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
have same := Matrix.masked_matmul_region_invariant radius ( fun _ _ => 1 )
( vmap ( contribution ( input s ) ) input ) ( vmap ( contribution ( input s ) ) other ) s
( fun t ht => congrArg ( contribution ( input s ) ) ( agree t ht ) ) hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s same : (fun values => ( matrix_mask radius fun x x_1 => 1 ) . matmul values ) ( vmap ( contribution ( input s ) ) input ) s =
(fun values => ( matrix_mask radius fun x x_1 => 1 ) . matmul values ) ( vmap ( contribution ( input s ) ) other ) s ⊢ (fun input => swa radius ( project_qkv input wq wk wv ) ) input s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s
exact ( masked input ) . trans
( same . trans ( by hidden : Nat seq : Nat radius : Nat wq : Matrix hidden hidden wk : Matrix hidden hidden wv : Matrix hidden hidden input : Fin seq → Vector hidden other : Fin seq → Vector hidden s : Fin seq agree : ∀ ( t : Fin seq ), InWindow radius s t → input t = other t center : input s = other s contribution : Vector hidden → Vector hidden → Vector hidden :=
fun query row j =>
( Vector.dot_product (fun d => query . dot_product ( wq . transpose d ) ) fun d => row . dot_product ( wk . transpose d ) ) *
row . dot_product ( wv . transpose j ) masked : ∀ ( x : Matrix seq hidden ),
swa radius ( project_qkv x wq wk wv ) s = ( matrix_mask radius fun x x_1 => 1 ) . matmul ( vmap ( contribution ( x s ) ) x ) s same : (fun values => ( matrix_mask radius fun x x_1 => 1 ) . matmul values ) ( vmap ( contribution ( input s ) ) input ) s =
(fun values => ( matrix_mask radius fun x x_1 => 1 ) . matmul values ) ( vmap ( contribution ( input s ) ) other ) s ⊢ (fun values => ( matrix_mask radius fun x x_1 => 1 ) . matmul values ) ( vmap ( contribution ( input s ) ) other ) s =
(fun input => swa radius ( project_qkv input wq wk wv ) ) other s simpa only [ center ] using ( masked other ) . symm All goals completed! 🐙 ) )
Flash Attention
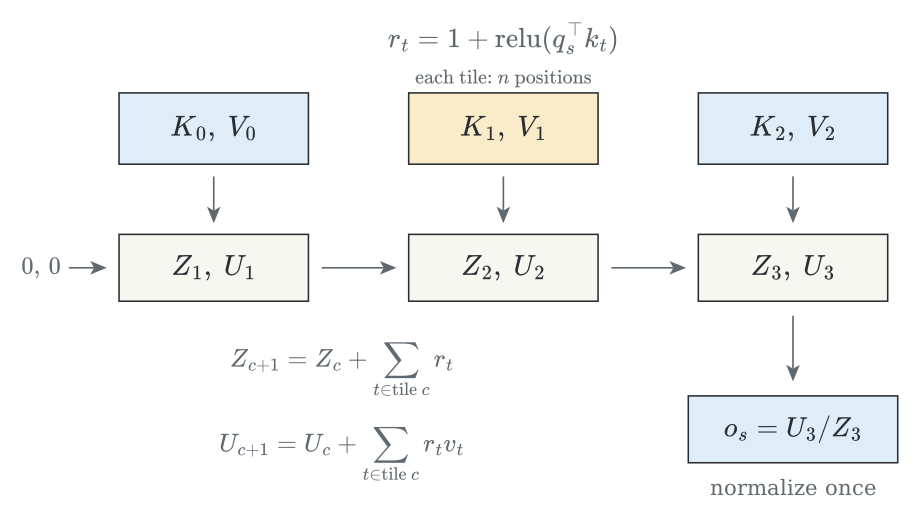
Once we have standard attention implemented, we can begin to consider optimizations.
Flash attention uses a tiling approach to split the full sequence into groups which
can be computed separately to reduce memory. We define a typed tiling.
Once we have this primitive, we can compute and aggregate a value for each tile.
structure FlashAcc ( hidden : Nat ) where
scoreSum : Rat
weighted : Vector hidden def flash_step ( r : α → Rat ) ( v : α → Vector hidden )
( state : FlashAcc hidden ) ( t : α ) : FlashAcc hidden :=
let score := r t
{ scoreSum := state . scoreSum + score
weighted := fun j => state . weighted j + score * v t j } def flash_attention ( tiles n : Nat )
( input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) ×
Matrix ( tiles * n ) hidden ) :
Matrix ( tiles * n ) hidden :=
let ⟨ ⟨ q , k ⟩ , v ⟩ := input
fun s =>
let r := fun t => 1 + relu ( Vector.sum ( fun d => q s d * k t d ) )
let initial : FlashAcc hidden := ⟨ 0 , fun _ => 0 ⟩
let state := tile_fold tiles n ( flash_step r v )
( fun t : Fin ( tiles * n ) => t ) initial
fun j => state . weighted j / state . scoreSum
For our equivalence proof, we need to define some basic properties of scans and sums.
These are not unique to Flash attention, but would be in a core mathematics library.
theorem scan_slice ( step : σ → α → σ ) ( xs : Fin n → α )
( start count : Nat ) ( h : start + count ≤ n ) ( initial : σ ) :
scan step ( slice start count h xs )
( scan step ( slice 0 start ( by α : Type u β : Type v δ : Type w σ : Sort ?u.7 n : Nat step : σ → α → σ xs : Fin n → α start : Nat count : Nat h : start + count ≤ n initial : σ ⊢ 0 + start ≤ n omega All goals completed! 🐙 ) xs ) initial ) =
scan step ( slice 0 ( start + count ) ( by α : Type u β : Type v δ : Type w σ : Sort ?u.7 n : Nat step : σ → α → σ xs : Fin n → α start : Nat count : Nat h : start + count ≤ n initial : σ ⊢ 0 + ( start + count ) ≤ n omega All goals completed! 🐙 ) xs ) initial := by α : Type u σ : Sort u_1 n : Nat step : σ → α → σ xs : Fin n → α start : Nat count : Nat h : start + count ≤ n initial : σ ⊢ scan step ( slice start count h xs ) ( scan step ( slice 0 start ⋯ xs ) initial ) =
scan step ( slice 0 ( start + count ) ⋯ xs ) initial
simp only [ scan , Fin.foldl_add , slice , select , Nat.add_zero , Fin.val_castLE ,
Fin.val_natAdd , Nat.add_comm ] All goals completed! 🐙 theorem scan_full ( step : σ → α → σ ) ( xs : Fin n → α ) ( initial : σ )
( h : count = n ) :
scan step ( slice 0 count ( by α : Type u β : Type v δ : Type w σ : Sort ?u.8 n : Nat count : Nat step : σ → α → σ xs : Fin n → α initial : σ h : count = n ⊢ 0 + count ≤ n omega All goals completed! 🐙 ) xs ) initial = scan step xs initial := by α : Type u σ : Sort u_1 n : Nat count : Nat step : σ → α → σ xs : Fin n → α initial : σ h : count = n ⊢ scan step ( slice 0 count ⋯ xs ) initial = scan step xs initial
subst count α : Type u σ : Sort u_1 n : Nat step : σ → α → σ xs : Fin n → α initial : σ ⊢ scan step ( slice 0 n ⋯ xs ) initial = scan step xs initial
rfl All goals completed! 🐙 theorem Vector.sum_succ ( f : Vector ( n + 1 ) ) :
f . sum = f 0 + Vector.sum ( fun i : Fin n => f i . succ ) := by n : Nat f : Vector ( n + 1 ) ⊢ f . sum = f 0 + sum fun i => f i . succ
simp [ Vector.sum , fori , List.ofFn_succ ] All goals completed! 🐙
theorem Vector.sum_mul ( f : Vector n ) ( c : Rat ) :
f . sum * c = Vector.sum ( fun i => f i * c ) := by n : Nat f : Vector n c : Rat ⊢ f . sum * c = sum fun i => f i * c
induction n with
| zero => zero c : Rat f : Vector 0 ⊢ f . sum * c = sum fun i => f i * c simp [ Vector.sum , fori , Rat.zero_mul ] All goals completed! 🐙
| succ n ih => succ c : Rat n : Nat ih : ∀ ( f : Vector n ), f . sum * c = sum fun i => f i * c f : Vector ( n + 1 ) ⊢ f . sum * c = sum fun i => f i * c rw [ Vector.sum_succ , succ c : Rat n : Nat ih : ∀ ( f : Vector n ), f . sum * c = sum fun i => f i * c f : Vector ( n + 1 ) ⊢ ( f 0 + sum fun i => f i . succ ) * c = sum fun i => f i * c All goals completed! 🐙 Rat.add_mul , succ c : Rat n : Nat ih : ∀ ( f : Vector n ), f . sum * c = sum fun i => f i * c f : Vector ( n + 1 ) ⊢ f 0 * c + ( sum fun i => f i . succ ) * c = sum fun i => f i * c All goals completed! 🐙 ih , succ c : Rat n : Nat ih : ∀ ( f : Vector n ), f . sum * c = sum fun i => f i * c f : Vector ( n + 1 ) ⊢ ( f 0 * c + sum fun i => f i . succ * c ) = sum fun i => f i * c All goals completed! 🐙 Vector.sum_succ succ c : Rat n : Nat ih : ∀ ( f : Vector n ), f . sum * c = sum fun i => f i * c f : Vector ( n + 1 ) ⊢ ( f 0 * c + sum fun i => f i . succ * c ) = f 0 * c + sum fun i => f i . succ * c All goals completed! 🐙 ] All goals completed! 🐙 theorem Vector.sum_last ( f : Vector ( n + 1 ) ) :
f . sum = Vector.sum ( fun i : Fin n => f i . castSucc ) + f ( Fin.last n ) := by n : Nat f : Vector ( n + 1 ) ⊢ f . sum = ( sum fun i => f i . castSucc ) + f ( Fin.last n )
simp only [ Vector.sum , fori , List.ofFn_succ_last , List.sum_append , List.sum_cons ,
List.sum_nil , Rat.add_zero ] All goals completed! 🐙
theorem Vector.sum_rev ( f : Vector n ) : Vector.sum ( fun t => f t . rev ) = f . sum := by n : Nat f : Vector n ⊢ ( sum fun t => f t . rev ) = f . sum
induction n with
| zero => zero f : Vector 0 ⊢ ( sum fun t => f t . rev ) = f . sum rfl All goals completed! 🐙
| succ n ih => succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( sum fun t => f t . rev ) = f . sum
rw [ Vector.sum_succ , succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = f . sum succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = ( sum fun i => f i . castSucc ) + f ( Fin.last n ) Vector.sum_last f succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = ( sum fun i => f i . castSucc ) + f ( Fin.last n ) succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = ( sum fun i => f i . castSucc ) + f ( Fin.last n ) ] succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = ( sum fun i => f i . castSucc ) + f ( Fin.last n )
have h := ih ( fun i => f i . castSucc ) succ n : Nat ih : ∀ ( f : Vector n ), ( sum fun t => f t . rev ) = f . sum f : Vector ( n + 1 ) h : ( sum fun t => f t . rev . castSucc ) = sum fun i => f i . castSucc ⊢ ( f ( Fin.rev 0 ) + sum fun i => f i . succ . rev ) = ( sum fun i => f i . castSucc ) + f ( Fin.last n )
simpa [ Fin.rev_succ , Rat.add_comm ] using
congrArg ( fun z => f ( Fin.last n ) + z ) h All goals completed! 🐙
theorem tile_fold_eq ( tiles n : Nat ) ( step : σ → α → σ )
( xs : Fin ( tiles * n ) → α ) ( initial : σ ) :
tile_fold tiles n step xs initial = scan step xs initial := by α : Type u σ : Sort u_1 tiles : Nat n : Nat step : σ → α → σ xs : Fin ( tiles * n ) → α initial : σ ⊢ tile_fold tiles n step xs initial = scan step xs initial
induction tiles generalizing initial with
| zero => zero α : Type u σ : Sort u_1 n : Nat step : σ → α → σ xs : Fin ( 0 * n ) → α initial : σ ⊢ tile_fold 0 n step xs initial = scan step xs initial simp [ tile_fold , scan ] All goals completed! 🐙
| succ tiles ih => succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ ⊢ tile_fold ( tiles + 1 ) n step xs initial = scan step xs initial
have shape : ( tiles + 1 ) * n = tiles * n + n := Nat.succ_mul tiles n succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ tile_fold ( tiles + 1 ) n step xs initial = scan step xs initial
rw [ tile_fold , succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan (fun state chunk => scan step chunk state ) ( tile n xs ) initial = scan step xs initial succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( tile n xs ( Fin.last tiles ) ) ( Fin.foldl tiles (fun x1 x2 => scan step ( tile n xs x2 . castSucc ) x1 ) initial ) =
scan step xs initial scan , succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ Fin.foldl ( tiles + 1 ) (fun state i => scan step ( tile n xs i ) state ) initial = scan step xs initial succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( tile n xs ( Fin.last tiles ) ) ( Fin.foldl tiles (fun x1 x2 => scan step ( tile n xs x2 . castSucc ) x1 ) initial ) =
scan step xs initial Fin.foldl_succ_last succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( tile n xs ( Fin.last tiles ) ) ( Fin.foldl tiles (fun x1 x2 => scan step ( tile n xs x2 . castSucc ) x1 ) initial ) =
scan step xs initial succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( tile n xs ( Fin.last tiles ) ) ( Fin.foldl tiles (fun x1 x2 => scan step ( tile n xs x2 . castSucc ) x1 ) initial ) =
scan step xs initial ] succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( tile n xs ( Fin.last tiles ) ) ( Fin.foldl tiles (fun x1 x2 => scan step ( tile n xs x2 . castSucc ) x1 ) initial ) =
scan step xs initial
change scan step ( slice ( tiles * n ) n ( by α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ tiles * n + n ≤ ( tiles + 1 ) * n omega All goals completed! 🐙 ) xs )
( tile_fold tiles n step ( slice 0 ( tiles * n ) ( by α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ 0 + tiles * n ≤ ( tiles + 1 ) * n omega All goals completed! 🐙 ) xs ) initial ) = _
rw [ ih , succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( slice ( tiles * n ) n ⋯ xs ) ( scan step ( slice 0 ( tiles * n ) ⋯ xs ) initial ) = scan step xs initial succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( slice 0 ( tiles * n + n ) ⋯ xs ) initial = scan step xs initial scan_slice succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( slice 0 ( tiles * n + n ) ⋯ xs ) initial = scan step xs initial succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( slice 0 ( tiles * n + n ) ⋯ xs ) initial = scan step xs initial ] succ α : Type u σ : Sort u_1 n : Nat step : σ → α → σ tiles : Nat ih : ∀ ( xs : Fin ( tiles * n ) → α ) ( initial : σ ), tile_fold tiles n step xs initial = scan step xs initial xs : Fin ( ( tiles + 1 ) * n ) → α initial : σ shape : ( tiles + 1 ) * n = tiles * n + n ⊢ scan step ( slice 0 ( tiles * n + n ) ⋯ xs ) initial = scan step xs initial
exact scan_full _ _ _ shape . symm All goals completed! 🐙
The main proof is that Flash attention is equivalent to our original attention.
This is done by showing a lemma over the internal fold that we are accumulating
the correct values.
private theorem flash_fold ( xs : Fin n → α )
( r : α → Rat ) ( v : α → Vector hidden )
( state : FlashAcc hidden ) :
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum ( fun i => r ( xs i ) )
weighted := fun j => state . weighted j +
Vector.sum ( fun i => r ( xs i ) * v ( xs i ) j ) } := by α : Type u n : Nat hidden : Nat xs : Fin n → α r : α → Rat v : α → Vector hidden state : FlashAcc hidden ⊢ scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j }
induction n generalizing state with
| zero => zero α : Type u hidden : Nat r : α → Rat v : α → Vector hidden xs : Fin 0 → α state : FlashAcc hidden ⊢ scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } cases state zero.mk α : Type u hidden : Nat r : α → Rat v : α → Vector hidden xs : Fin 0 → α scoreSum✝ : Rat weighted✝ : Vector hidden ⊢ scan ( flash_step r v ) xs { scoreSum := scoreSum✝ , weighted := weighted✝ } =
{ scoreSum := { scoreSum := scoreSum✝ , weighted := weighted✝ } . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j =>
{ scoreSum := scoreSum✝ , weighted := weighted✝ } . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } ; simp [ scan , Vector.sum , fori ] All goals completed! 🐙
| succ n ih => succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j }
simp only [ scan , Fin.foldl_succ ] succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ Fin.foldl n (fun x i => flash_step r v x ( xs i . succ ) ) ( flash_step r v state ( xs 0 ) ) =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j }
change scan ( flash_step r v ) ( fun i => xs i . succ )
( flash_step r v state ( xs 0 ) ) = _ succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ scan ( flash_step r v ) (fun i => xs i . succ ) ( flash_step r v state ( xs 0 ) ) =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j }
rw [ ih succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ { scoreSum := ( flash_step r v state ( xs 0 ) ) . scoreSum + Vector.sum fun i => r ( xs i . succ ) ,
weighted := fun j =>
( flash_step r v state ( xs 0 ) ) . weighted j + Vector.sum fun i => r ( xs i . succ ) * v ( xs i . succ ) j } =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ { scoreSum := ( flash_step r v state ( xs 0 ) ) . scoreSum + Vector.sum fun i => r ( xs i . succ ) ,
weighted := fun j =>
( flash_step r v state ( xs 0 ) ) . weighted j + Vector.sum fun i => r ( xs i . succ ) * v ( xs i . succ ) j } =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } ] succ α : Type u hidden : Nat r : α → Rat v : α → Vector hidden n : Nat ih : ∀ ( xs : Fin n → α ) ( state : FlashAcc hidden ),
scan ( flash_step r v ) xs state =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j } xs : Fin ( n + 1 ) → α state : FlashAcc hidden ⊢ { scoreSum := ( flash_step r v state ( xs 0 ) ) . scoreSum + Vector.sum fun i => r ( xs i . succ ) ,
weighted := fun j =>
( flash_step r v state ( xs 0 ) ) . weighted j + Vector.sum fun i => r ( xs i . succ ) * v ( xs i . succ ) j } =
{ scoreSum := state . scoreSum + Vector.sum fun i => r ( xs i ) ,
weighted := fun j => state . weighted j + Vector.sum fun i => r ( xs i ) * v ( xs i ) j }
simp [ Vector.sum_succ , flash_step , Rat.add_assoc ] All goals completed! 🐙 theorem flash_attention_eq ( tiles n : Nat )
( input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) ×
Matrix ( tiles * n ) hidden ) :
flash_attention tiles n input = attention_layer input := by hidden : Nat tiles : Nat n : Nat input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) × Matrix ( tiles * n ) hidden ⊢ flash_attention tiles n input = attention_layer input
rcases input with ⟨ ⟨ q , k ⟩ , v ⟩ hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden ⊢ flash_attention tiles n ( ( q , k ) , v ) = attention_layer ( ( q , k ) , v )
funext s j hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden ⊢ flash_attention tiles n ( ( q , k ) , v ) s j = attention_layer ( ( q , k ) , v ) s j
simp only [ flash_attention , tile_fold_eq , flash_fold ,
Rat.zero_add ] hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden ⊢ ( ( Vector.sum fun i => ( 1 + relu ( Vector.sum fun d => q s d * k i d ) ) * v i j ) /
Vector.sum fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ) =
attention_layer ( ( q , k ) , v ) s j
let r := fun t => 1 + relu ( Vector.sum ( fun d => q s d * k t d ) ) hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden r : Fin ( tiles * n ) → Rat := fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ⊢ ( ( Vector.sum fun i => ( 1 + relu ( Vector.sum fun d => q s d * k i d ) ) * v i j ) /
Vector.sum fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ) =
attention_layer ( ( q , k ) , v ) s j
change Vector.sum ( fun t => r t * v t j ) / Vector.sum r =
Vector.sum ( fun t => ( r t / Vector.sum r ) * v t j ) hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden r : Fin ( tiles * n ) → Rat := fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ⊢ ( Vector.sum fun t => r t * v t j ) / Vector.sum r = Vector.sum fun t => r t / Vector.sum r * v t j
simp only [ Rat.div_def , Vector.sum_mul ] hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden r : Fin ( tiles * n ) → Rat := fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ⊢ ( Vector.sum fun i => r i * v i j * ( Vector.sum r ) ⁻¹ ) = Vector.sum fun t => r t * ( Vector.sum r ) ⁻¹ * v t j
apply congrArg Vector.sum hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden r : Fin ( tiles * n ) → Rat := fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) ⊢ (fun i => r i * v i j * ( Vector.sum r ) ⁻¹ ) = fun t => r t * ( Vector.sum r ) ⁻¹ * v t j
funext t hidden : Nat tiles : Nat n : Nat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden r : Fin ( tiles * n ) → Rat := fun t => 1 + relu ( Vector.sum fun d => q s d * k t d ) t : Fin ( tiles * n ) ⊢ r t * v t j * ( Vector.sum r ) ⁻¹ = r t * ( Vector.sum r ) ⁻¹ * v t j
grind All goals completed! 🐙
State Space Models
Another alternative to standard attention is to use a state space model or
linear attention approach. These can be defined by the following recurrence.
def ssm_scan ( a : Rat ) ( values : Vector n ) ( initial : Rat := 0 ) : Rat :=
scan ( fun state x => a * state + x ) values initial def ssm_state ( a : Rat ) ( updates : Fin n → Matrix hidden hidden )
( incoming : Matrix hidden hidden := fun _ _ => 0 ) : Matrix hidden hidden :=
fun d j => ssm_scan a ( fun t => updates t d j ) ( incoming d j ) def ssm_layer ( a : Rat ) : Mixer seq hidden :=
fun input =>
let ⟨ ⟨ q , k ⟩ , v ⟩ := input
let updates := fun t => ( fun d j => k t d * v t j : Matrix hidden hidden )
fun s =>
( ssm_state a ( slice 0 ( s . val + 1 ) ( by α : Type u β : Type v δ : Type w seq : Nat hidden : Nat a : Rat input : ( Matrix seq hidden × Matrix seq hidden ) × Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden v : Matrix seq hidden updates : Fin seq → Fin hidden → Fin hidden → Rat := fun t d j => k t d * v t j s : Fin seq ⊢ 0 + ( ↑ s + 1 ) ≤ seq omega All goals completed! 🐙 ) updates ) ) . transpose . matvec ( q s )
theorem scan_weighted ( a : Rat ) ( values : Vector n ) ( z : Rat ) :
ssm_scan a values z =
a ^ n * z + Vector.sum ( fun t => a ^ ( n - 1 - t . val ) * values t ) := by n : Nat a : Rat values : Vector n z : Rat ⊢ ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t
induction n generalizing z with
| zero => zero a : Rat values : Vector 0 z : Rat ⊢ ssm_scan a values z = a ^ 0 * z + Vector.sum fun t => a ^ ( 0 - 1 - ↑ t ) * values t simp [ ssm_scan , scan , Vector.sum , fori ] All goals completed! 🐙
| succ n ih => succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ssm_scan a values z = a ^ ( n + 1 ) * z + Vector.sum fun t => a ^ ( n + 1 - 1 - ↑ t ) * values t
simp only [ ssm_scan , scan , Fin.foldl_succ ] succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ Fin.foldl n (fun x i => a * x + values i . succ ) ( a * z + values 0 ) =
a ^ ( n + 1 ) * z + Vector.sum fun t => a ^ ( n + 1 - 1 - ↑ t ) * values t
change ssm_scan a ( fun i : Fin n => values i . succ ) ( a * z + values 0 ) = _ succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ssm_scan a (fun i => values i . succ ) ( a * z + values 0 ) =
a ^ ( n + 1 ) * z + Vector.sum fun t => a ^ ( n + 1 - 1 - ↑ t ) * values t
rw [ ih , succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ( a ^ n * ( a * z + values 0 ) + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t . succ ) =
a ^ ( n + 1 ) * z + Vector.sum fun t => a ^ ( n + 1 - 1 - ↑ t ) * values t succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ( a ^ n * ( a * z + values 0 ) + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t . succ ) =
a ^ ( n + 1 ) * z + ( a ^ ( n + 1 - 1 - ↑ 0 ) * values 0 + Vector.sum fun i => a ^ ( n + 1 - 1 - ↑ i . succ ) * values i . succ ) Vector.sum_succ succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ( a ^ n * ( a * z + values 0 ) + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t . succ ) =
a ^ ( n + 1 ) * z + ( a ^ ( n + 1 - 1 - ↑ 0 ) * values 0 + Vector.sum fun i => a ^ ( n + 1 - 1 - ↑ i . succ ) * values i . succ ) succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ( a ^ n * ( a * z + values 0 ) + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t . succ ) =
a ^ ( n + 1 ) * z + ( a ^ ( n + 1 - 1 - ↑ 0 ) * values 0 + Vector.sum fun i => a ^ ( n + 1 - 1 - ↑ i . succ ) * values i . succ ) ] succ a : Rat n : Nat ih : ∀ ( values : Vector n ) ( z : Rat ), ssm_scan a values z = a ^ n * z + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t values : Vector ( n + 1 ) z : Rat ⊢ ( a ^ n * ( a * z + values 0 ) + Vector.sum fun t => a ^ ( n - 1 - ↑ t ) * values t . succ ) =
a ^ ( n + 1 ) * z + ( a ^ ( n + 1 - 1 - ↑ 0 ) * values 0 + Vector.sum fun i => a ^ ( n + 1 - 1 - ↑ i . succ ) * values i . succ )
simp [ Nat.sub_sub , Nat.add_comm , Rat.pow_succ ,
Rat.mul_add , Rat.mul_assoc , Rat.add_assoc ] All goals completed! 🐙
Unlike vanilla attention, state space models clearly induce an ordering on
the sequence in the multiplicative term a. However, in the special case
where that term is 1 and we use a bidirectional SSM, we can show that the
permutation equivariance remains.
def bidirectional_ssm_scan ( a : Rat ) ( values : Vector n ) : Vector n :=
fun s =>
let suffix := slice s . val ( n - s . val ) ( by α : Type u β : Type v δ : Type w n : Nat a : Rat values : Vector n s : Fin n ⊢ ↑ s + ( n - ↑ s ) ≤ n omega All goals completed! 🐙 ) values
ssm_scan a ( slice 0 ( s . val + 1 ) ( by α : Type u β : Type v δ : Type w n : Nat a : Rat values : Vector n s : Fin n suffix : Fin ( n - ↑ s ) → Rat := slice (↑ s ) ( n - ↑ s ) ⋯ values ⊢ 0 + ( ↑ s + 1 ) ≤ n omega All goals completed! 🐙 ) values ) +
ssm_scan a ( fun t => suffix t . rev ) def bidirectional_ssm_layer ( α : Rat ) : Mixer seq hidden :=
fun input =>
let ⟨ ⟨ q , k ⟩ , v ⟩ := input
fun s =>
let state : Matrix hidden hidden := fun d j =>
bidirectional_ssm_scan α ( fun t => k t d * v t j ) s
state . transpose . matvec ( q s )
theorem bidirectional_scan_one ( f : Vector n ) ( s : Fin n ) :
bidirectional_ssm_scan 1 f s = f . sum + f s := by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s
dsimp [ Vector ] at f n : Nat f : Fin n → Rat s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s
have one_pow ( m : Nat ) : ( 1 : Rat ) ^ m = 1 := by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ bidirectional_ssm_scan 1 f s = Vector.sum f + f s
induction m zero n : Nat f : Fin n → Rat s : Fin n ⊢ 1 ^ 0 = 1 succ n : Nat f : Fin n → Rat s : Fin n n✝ : Nat a✝ : 1 ^ n✝ = 1 ⊢ 1 ^ ( n✝ + 1 ) = 1 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ bidirectional_ssm_scan 1 f s = Vector.sum f + f s <;> zero n : Nat f : Fin n → Rat s : Fin n ⊢ 1 ^ 0 = 1 succ n : Nat f : Fin n → Rat s : Fin n n✝ : Nat a✝ : 1 ^ n✝ = 1 ⊢ 1 ^ ( n✝ + 1 ) = 1 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ bidirectional_ssm_scan 1 f s = Vector.sum f + f s simp_all [ Rat.pow_succ ] n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ bidirectional_ssm_scan 1 f s = Vector.sum f + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ bidirectional_ssm_scan 1 f s = Vector.sum f + f s
simp only [ bidirectional_ssm_scan , scan_weighted , one_pow ,
Rat.one_mul , Rat.mul_zero , Rat.zero_add ] n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ ( ( Vector.sum fun t => slice 0 ( ↑ s + 1 ) ⋯ f t ) + Vector.sum fun t => slice (↑ s ) ( n - ↑ s ) ⋯ f t . rev ) = Vector.sum f + f s
rw [ Vector.sum_rev n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ ( Vector.sum fun t => slice 0 ( ↑ s + 1 ) ⋯ f t ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ ( Vector.sum fun t => slice 0 ( ↑ s + 1 ) ⋯ f t ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ] n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ ( Vector.sum fun t => slice 0 ( ↑ s + 1 ) ⋯ f t ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
rw [ show Vector.sum ( slice 0 ( s . val + 1 ) ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ 0 + ( ↑ s + 1 ) ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) =
Vector.sum ( slice 0 s . val ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ 0 + ↑ s ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) + f s by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
exact Vector.sum_last ( slice 0 ( s . val + 1 ) ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ 0 + ( ↑ s + 1 ) ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) ] n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
have split := Vector.sum_split
( values := fun t : Fin ( s . val + ( n - s . val ) ) => f ⟨ t . val , by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 t : Fin ( ↑ s + ( n - ↑ s ) ) ⊢ ↑ t < n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ⟩ ) n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
have total :
Vector.sum ( fun t : Fin ( s . val + ( n - s . val ) ) => f ⟨ t . val , by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ t : Fin ( ↑ s + ( n - ↑ s ) ) ⊢ ↑ t < n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ⟩ ) =
Vector.sum f := by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
have full ( m : Nat ) ( h : m = n ) :
Vector.sum ( slice 0 m ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ m : Nat h : m = n ⊢ 0 + m ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) = Vector.sum f := by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
subst m n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ⊢ Vector.sum ( slice 0 n ⋯ f ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
rfl n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
exact full _ ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ full : ∀ ( m : Nat ) ( h : m = n ), Vector.sum ( slice 0 m ⋯ f ) = Vector.sum f ⊢ ↑ s + ( n - ↑ s ) = n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
rw [ total n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ] at split n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
have split' : Vector.sum ( slice 0 s . val ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ 0 + ↑ s ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) +
Vector.sum ( slice s . val ( n - s . val ) ( by n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f ⊢ ↑ s + ( n - ↑ s ) ≤ n n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s omega All goals completed! 🐙 n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s ) f ) = Vector.sum f := by n : Nat f : Vector n s : Fin n ⊢ bidirectional_ssm_scan 1 f s = f . sum + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
simpa [ Vector.sum , slice , select , Nat.add_comm ] using split n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s n : Nat f : Fin n → Rat s : Fin n one_pow : ∀ ( m : Nat ), 1 ^ m = 1 split : Vector.sum ( select (fun i => Fin.castAdd ( n - ↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) +
Vector.sum ( select (fun i => Fin.natAdd (↑ s ) i ) fun t => f ⟨ ↑ t , ⋯ ⟩ ) =
Vector.sum f total : ( Vector.sum fun t => f ⟨ ↑ t , ⋯ ⟩ ) = Vector.sum f split' : Vector.sum ( slice 0 ↑ s ⋯ f ) + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f ⊢ Vector.sum ( slice 0 ↑ s ⋯ f ) + f s + Vector.sum ( slice (↑ s ) ( n - ↑ s ) ⋯ f ) = Vector.sum f + f s
grind All goals completed! 🐙
theorem bidirectional_ssm_layer_permute :
PermuteEquivariant
( bidirectional_ssm_layer ( seq := seq ) ( hidden := hidden ) 1 )
permute_qkv := by seq : Nat hidden : Nat ⊢ PermuteEquivariant ( bidirectional_ssm_layer 1 ) permute_qkv permute
intro π input seq : Nat hidden : Nat π : PositionPermutation seq input : ( Matrix seq hidden × Matrix seq hidden ) × Matrix seq hidden ⊢ (fun { shape } => bidirectional_ssm_layer 1 ) ( permute_qkv π input ) =
permute π ( (fun { shape } => bidirectional_ssm_layer 1 ) input )
rcases input with ⟨ ⟨ q , k ⟩ , v ⟩ seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden ⊢ (fun { shape } => bidirectional_ssm_layer 1 ) ( permute_qkv π ( ( q , k ) , v ) ) =
permute π ( (fun { shape } => bidirectional_ssm_layer 1 ) ( ( q , k ) , v ) )
funext s j seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden ⊢ (fun { shape } => bidirectional_ssm_layer 1 ) ( permute_qkv π ( ( q , k ) , v ) ) s j =
permute π ( (fun { shape } => bidirectional_ssm_layer 1 ) ( ( q , k ) , v ) ) s j
apply congrArg Vector.sum seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden ⊢ Matrix.transpose (fun d j => bidirectional_ssm_scan 1 (fun t => permute π k t d * permute π v t j ) s ) j *
permute π q s =
Matrix.transpose (fun d j => bidirectional_ssm_scan 1 (fun t => k t d * v t j ) ( π . index s ) ) j * q ( π . index s )
funext d seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( Matrix.transpose (fun d j => bidirectional_ssm_scan 1 (fun t => permute π k t d * permute π v t j ) s ) j *
permute π q s )
d =
( Matrix.transpose (fun d j => bidirectional_ssm_scan 1 (fun t => k t d * v t j ) ( π . index s ) ) j * q ( π . index s ) ) d
change bidirectional_ssm_scan 1 ( fun t => k ( π . index t ) d * v ( π . index t ) j ) s *
q ( π . index s ) d =
bidirectional_ssm_scan 1 ( fun t => k t d * v t j ) ( π . index s ) * q ( π . index s ) d seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ bidirectional_ssm_scan 1 (fun t => k ( π . index t ) d * v ( π . index t ) j ) s * q ( π . index s ) d =
bidirectional_ssm_scan 1 (fun t => k t d * v t j ) ( π . index s ) * q ( π . index s ) d
rw [ bidirectional_scan_one , seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( ( Vector.sum fun t => k ( π . index t ) d * v ( π . index t ) j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d =
bidirectional_ssm_scan 1 (fun t => k t d * v t j ) ( π . index s ) * q ( π . index s ) d seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( ( Vector.sum fun t => k ( π . index t ) d * v ( π . index t ) j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d =
( ( Vector.sum fun t => k t d * v t j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d bidirectional_scan_one seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( ( Vector.sum fun t => k ( π . index t ) d * v ( π . index t ) j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d =
( ( Vector.sum fun t => k t d * v t j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( ( Vector.sum fun t => k ( π . index t ) d * v ( π . index t ) j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d =
( ( Vector.sum fun t => k t d * v t j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d ] seq : Nat hidden : Nat π : PositionPermutation seq v : Matrix seq hidden q : Matrix seq hidden k : Matrix seq hidden s : Fin seq j : Fin hidden d : Fin hidden ⊢ ( ( Vector.sum fun t => k ( π . index t ) d * v ( π . index t ) j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d =
( ( Vector.sum fun t => k t d * v t j ) + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d
exact congrArg
( fun total => ( total + k ( π . index s ) d * v ( π . index s ) j ) * q ( π . index s ) d )
( permute_sum π ( fun t => k t d * v t j ) ) All goals completed! 🐙
These models also have the property that we can chunk them into groups which
can be computed separately. Here we consider a simplified version of chunking
in order to distribute across machines.
We can prove that this yields the same result as our simple implementation.
theorem ssm_chunk_carry_eq ( tiles n : Nat ) ( a : Rat )
( values : Vector ( tiles * n ) ) :
ssm_chunk_carry tiles n a values = ssm_scan a values := by tiles : Nat n : Nat a : Rat values : Vector ( tiles * n ) ⊢ ssm_chunk_carry tiles n a values = ssm_scan a values
simp only [ ssm_chunk_carry , ssm_chunk , ← scan_weighted , ssm_scan ] tiles : Nat n : Nat a : Rat values : Vector ( tiles * n ) ⊢ scan (fun state values => scan (fun state x => a * state + x ) values state ) ( tile n values ) 0 =
scan (fun state x => a * state + x ) values 0
exact tile_fold_eq tiles n _ values 0 All goals completed! 🐙
theorem chunkwise_ssm_layer_eq ( tiles n : Nat ) ( a : Rat )
( input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) ×
Matrix ( tiles * n ) hidden ) :
chunkwise_ssm_layer tiles n a input = ssm_layer a input := by hidden : Nat tiles : Nat n : Nat a : Rat input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) × Matrix ( tiles * n ) hidden ⊢ chunkwise_ssm_layer tiles n a input = ssm_layer a input
rcases input with ⟨ ⟨ q , k ⟩ , v ⟩ hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden ⊢ chunkwise_ssm_layer tiles n a ( ( q , k ) , v ) = ssm_layer a ( ( q , k ) , v )
funext s j hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden ⊢ chunkwise_ssm_layer tiles n a ( ( q , k ) , v ) s j = ssm_layer a ( ( q , k ) , v ) s j
apply congrArg Vector.sum hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden ⊢ Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s =
( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s
funext d hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d
let updates : Vector ( tiles * n ) := fun t => k t d * v t j hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d
have bound : s . val / n * n + ( s . val % n + 1 ) ≤ tiles * n := by hidden : Nat tiles : Nat n : Nat a : Rat input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) × Matrix ( tiles * n ) hidden ⊢ chunkwise_ssm_layer tiles n a input = ssm_layer a input hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d
have := Nat.div_add_mod' s . val n hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j this : ↑ s / n * n + ↑ s % n = ↑ s ⊢ ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d
omega hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ( Matrix.transpose
(fun d j =>
have updates := fun t => k t d * v t j ;
have incoming := ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ;
ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) ⋯ updates ) incoming )
j *
q s )
d =
( ( ssm_state a ( slice 0 ( ↑ s + 1 ) ⋯ fun t d j => k t d * v t j ) ) . transpose j * q s ) d
change ssm_chunk a ( slice ( s . val / n * n ) ( s . val % n + 1 ) bound updates )
( ssm_chunk_carry ( s . val / n ) n a
( slice 0 ( s . val / n * n ) ( by hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ 0 + ↑ s / n * n ≤ tiles * n omega All goals completed! 🐙 ) updates ) ) * q s d =
ssm_scan a ( slice 0 ( s . val + 1 ) ( by hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ 0 + ( ↑ s + 1 ) ≤ tiles * n omega All goals completed! 🐙 ) updates ) * q s d
apply congrArg ( fun state => state * q s d ) hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates )
( ssm_chunk_carry ( ↑ s / n ) n a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
rw [ ssm_chunk_carry_eq hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) ] hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_chunk a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
change ( a ^ _ * _ + _ ) = _ hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ( a ^ ( ↑ s % n + 1 ) * ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) +
Vector.sum fun t => a ^ ( ↑ s % n + 1 - 1 - ↑ t ) * slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates t ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
rw [ ← scan_weighted hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_scan a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_scan a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) ] hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ ssm_scan a ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates ) ( ssm_scan a ( slice 0 ( ↑ s / n * n ) ⋯ updates ) ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
change scan ( fun state x => a * state + x ) _
( scan ( fun state x => a * state + x ) _ 0 ) = _ hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ scan (fun state x => a * state + x ) ( slice ( ↑ s / n * n ) ( ↑ s % n + 1 ) bound updates )
( scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n ) ⋯ updates ) 0 ) =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
rw [ scan_slice hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) ] hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
have offset : s . val / n * n + ( s . val % n + 1 ) = s . val + 1 := by hidden : Nat tiles : Nat n : Nat a : Rat input : ( Matrix ( tiles * n ) hidden × Matrix ( tiles * n ) hidden ) × Matrix ( tiles * n ) hidden ⊢ chunkwise_ssm_layer tiles n a input = ssm_layer a input hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n offset : ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
have := Nat.div_add_mod' s . val n hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n this : ↑ s / n * n + ↑ s % n = ↑ s ⊢ ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n offset : ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
omega hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n offset : ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates ) hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n offset : ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 ⊢ scan (fun state x => a * state + x ) ( slice 0 ( ↑ s / n * n + ( ↑ s % n + 1 ) ) ⋯ updates ) 0 =
ssm_scan a ( slice 0 ( ↑ s + 1 ) ⋯ updates )
exact scan_full _ ( slice 0 ( s . val + 1 ) ( by hidden : Nat tiles : Nat n : Nat a : Rat v : Matrix ( tiles * n ) hidden q : Matrix ( tiles * n ) hidden k : Matrix ( tiles * n ) hidden s : Fin ( tiles * n ) j : Fin hidden d : Fin hidden updates : Vector ( tiles * n ) := fun t => k t d * v t j bound : ↑ s / n * n + ( ↑ s % n + 1 ) ≤ tiles * n offset : ↑ s / n * n + ( ↑ s % n + 1 ) = ↑ s + 1 ⊢ 0 + ( ↑ s + 1 ) ≤ tiles * n omega All goals completed! 🐙 ) updates ) 0 offset
Conclusion
This blog considers the use of Lean as a method to verify elementary properties
about Transformers and related models. There are many additional things one
might consider here, including bounding errors introduced from quantization,
aggregation, backpropagation, and training-inference mismatch. Additionally,
there are likely many ways to simplify these proofs or develop libraries to
make them more minimal.
At a high level, the main recent change is not the machinery for proving these
properties; it is the ease with which a person can specify "what" they want to
be proven and receive a certificate that a property is true. Understanding how
that interface should work and how it can be used will be an extremely
interesting challenge over the next year.